GeminiDB

GeminiDB Cassandra API

A high-performance wide-column database for lightweight, high-concurrency workloads, suited to small and medium-sized businesses

High throughputHigh reliability
$989.12 USD/month (for reference only)
Specifications
4 vCPUs | 16 GB; 3 nodes
Storage
500 GB

GeminiDB DynamoDB-Compatible API

A high-performance key-value and document database for flexible data models and high-concurrency workloads in small businesses

High concurrencyLow latency
$594.56 USD/month (for reference only)
Specifications
2 vCPUs | 8 GB; 3 nodes
Storage
500 GB

GeminiDB Influx API

A high-performance time-series database for high-concurrency writes and real-time queries at small businesses
Low costStreaming analytics
$434.56 USD/month (for reference only)
Specifications
2 vCPUs | 8 GB; 3 nodes
Storage
100 GB

Why Huawei Cloud GeminiDB?

Why Huawei Cloud GeminiDB?

Scalability

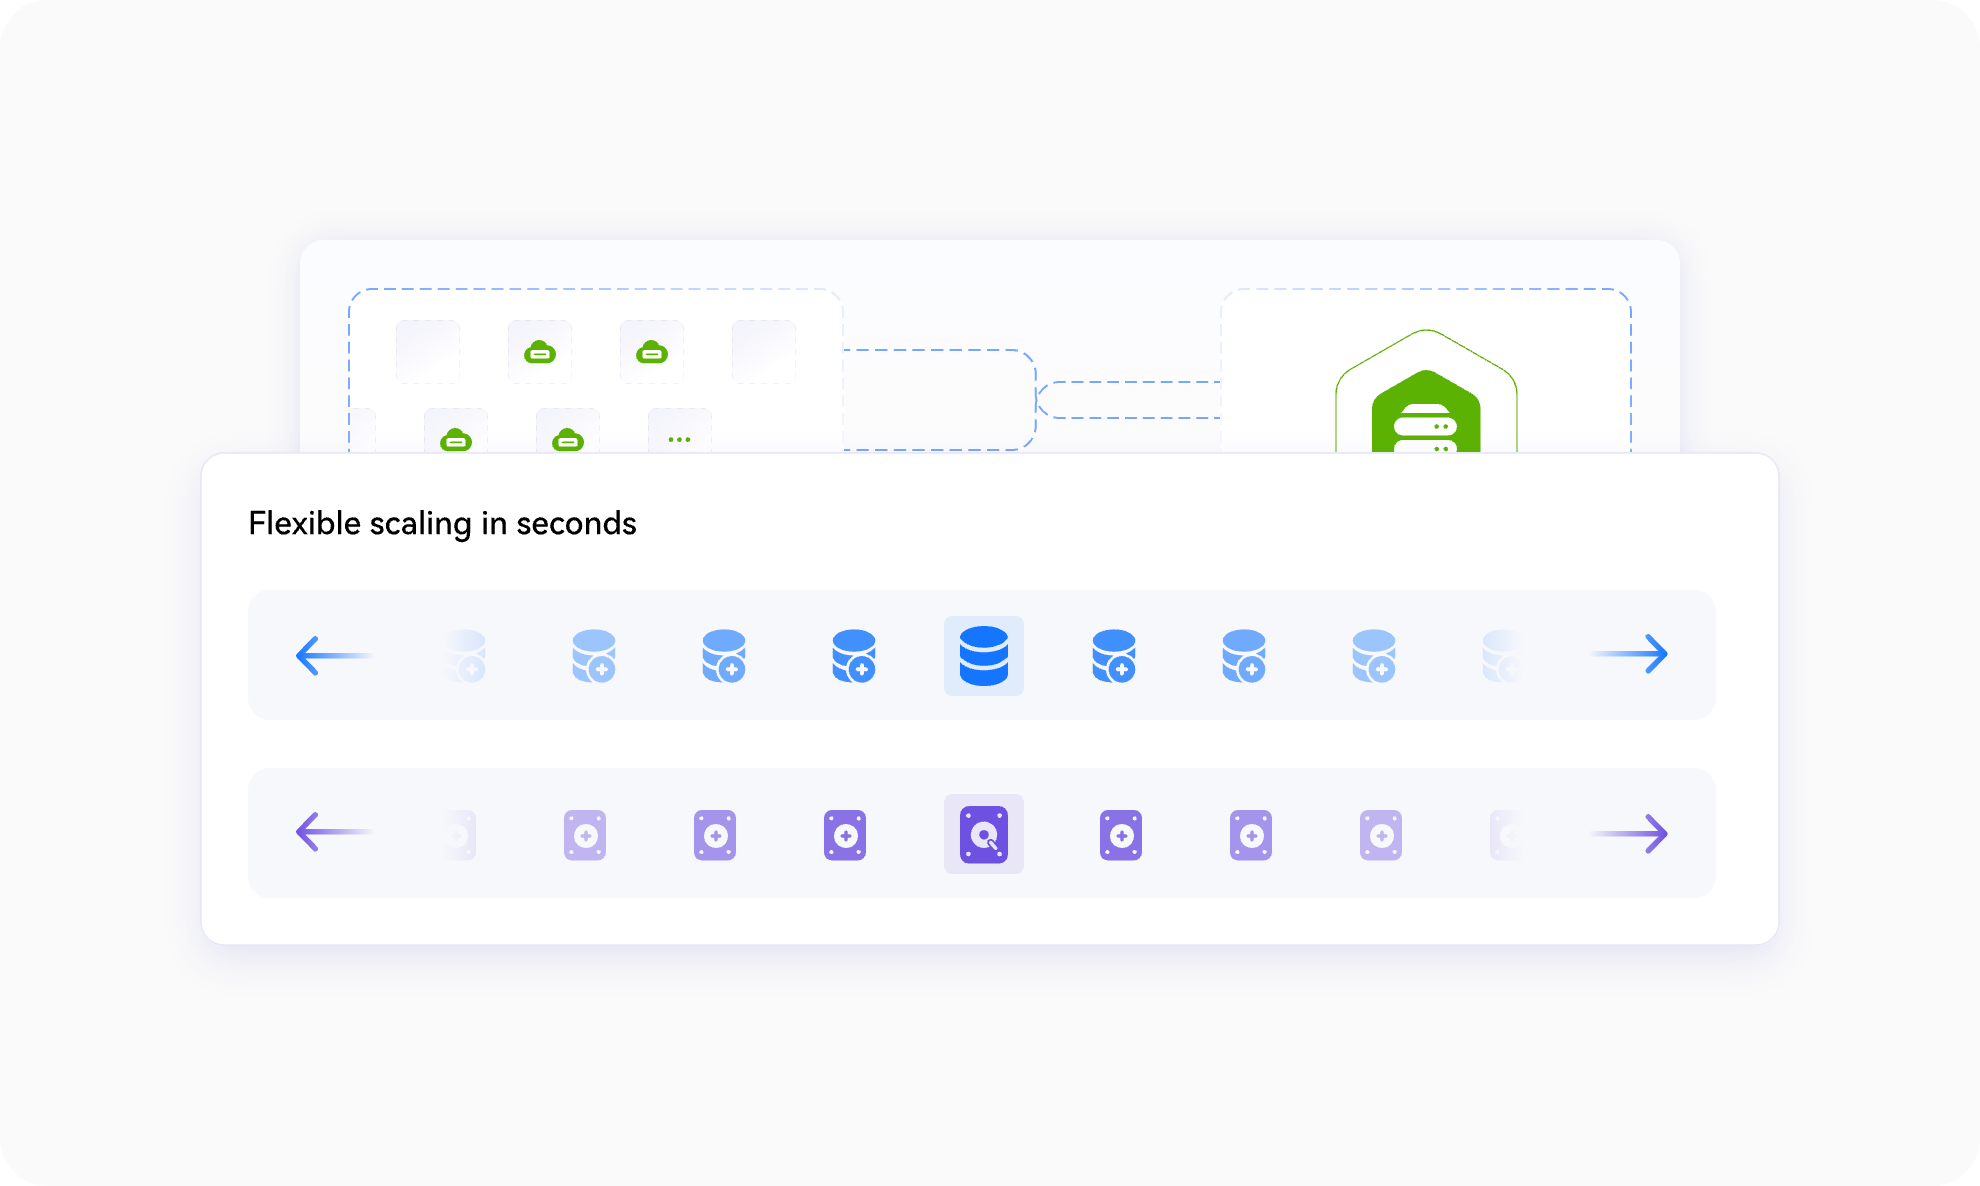
Shared-nothing and shared storage architecture: Stateless compute nodes share a stateful distributed storage engine. 

High resource utilization: Built-in proxy clusters support dynamic data load balancing.

Elastic scaling: Compute nodes can be added in minutes and storage can be scaled up in seconds.
Scalability

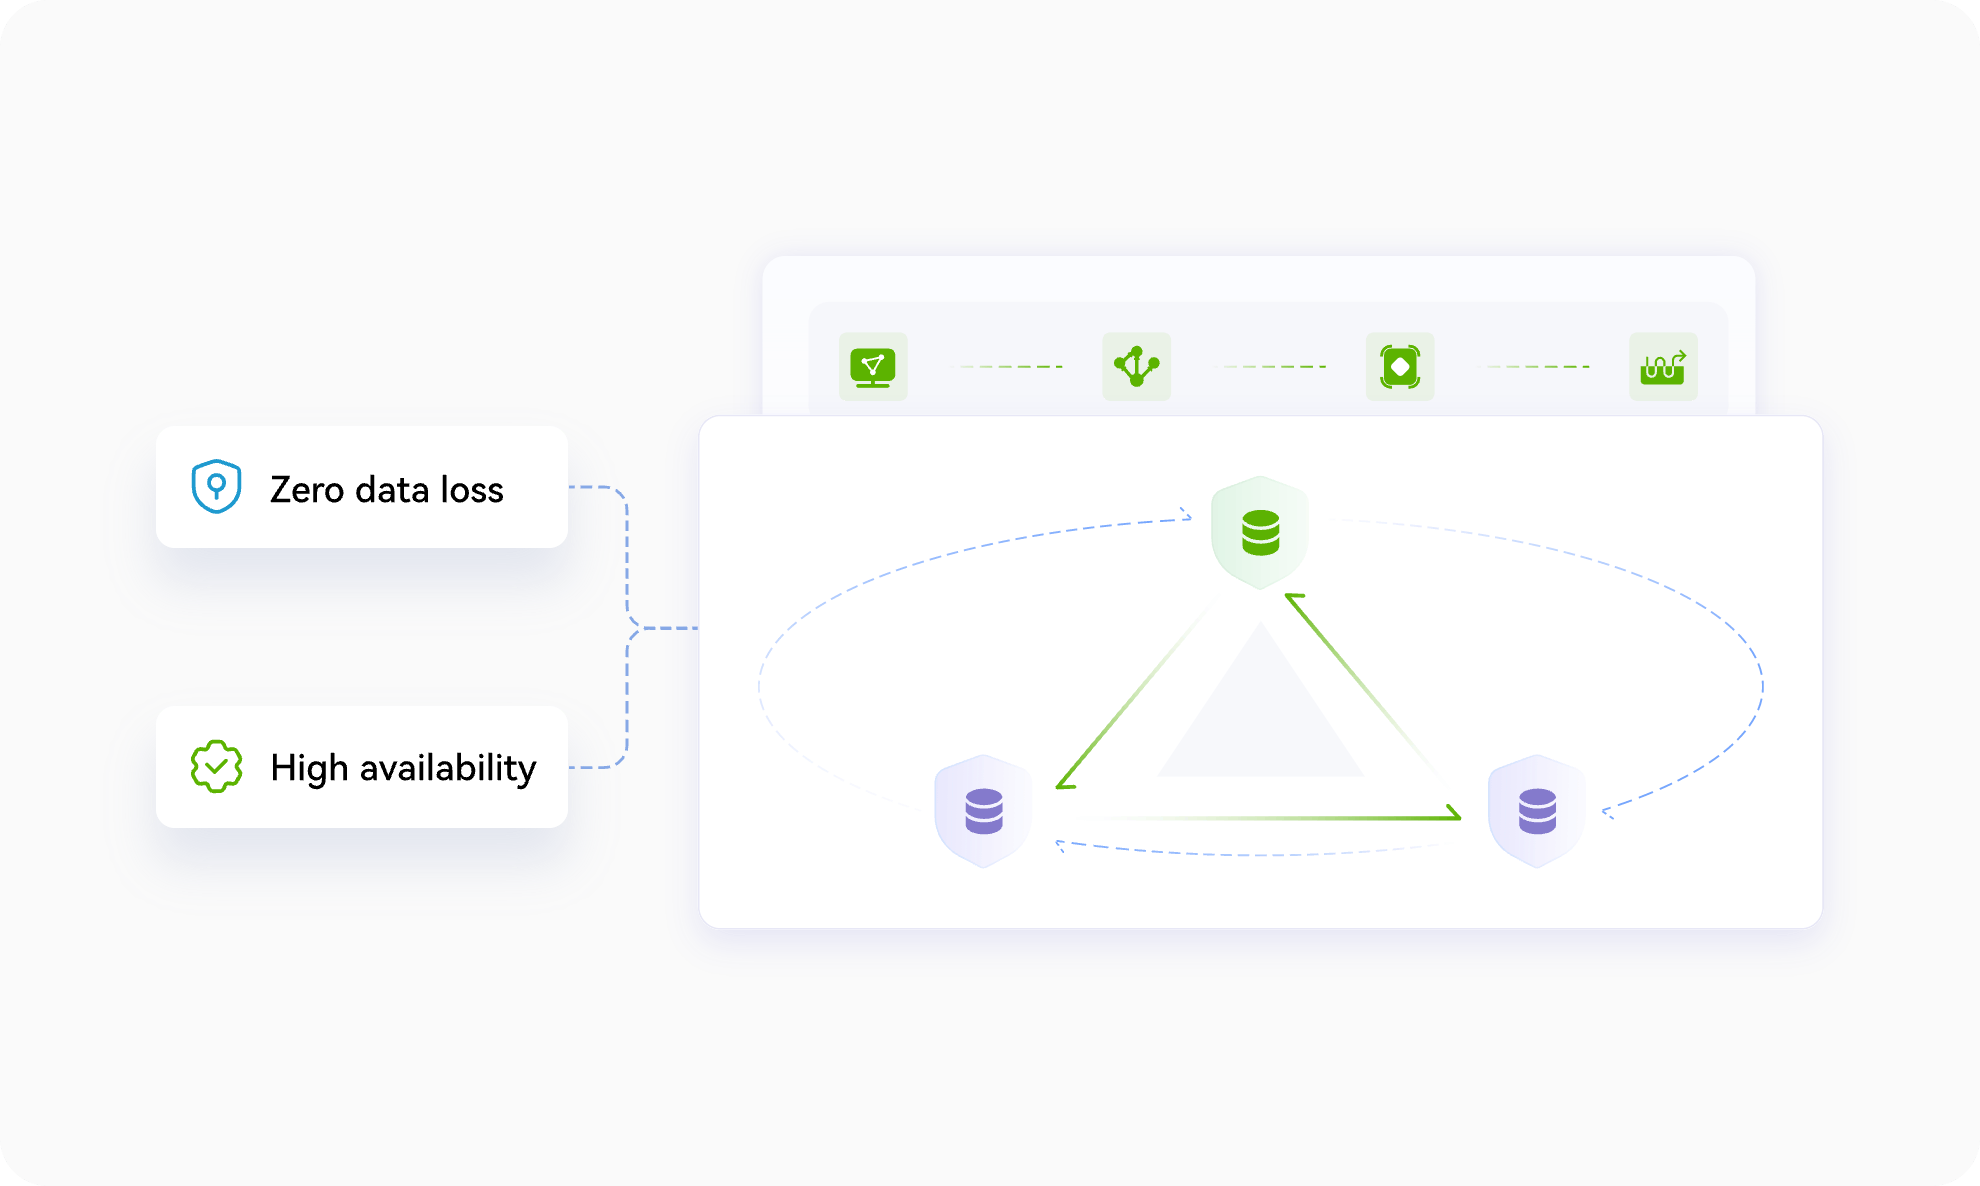
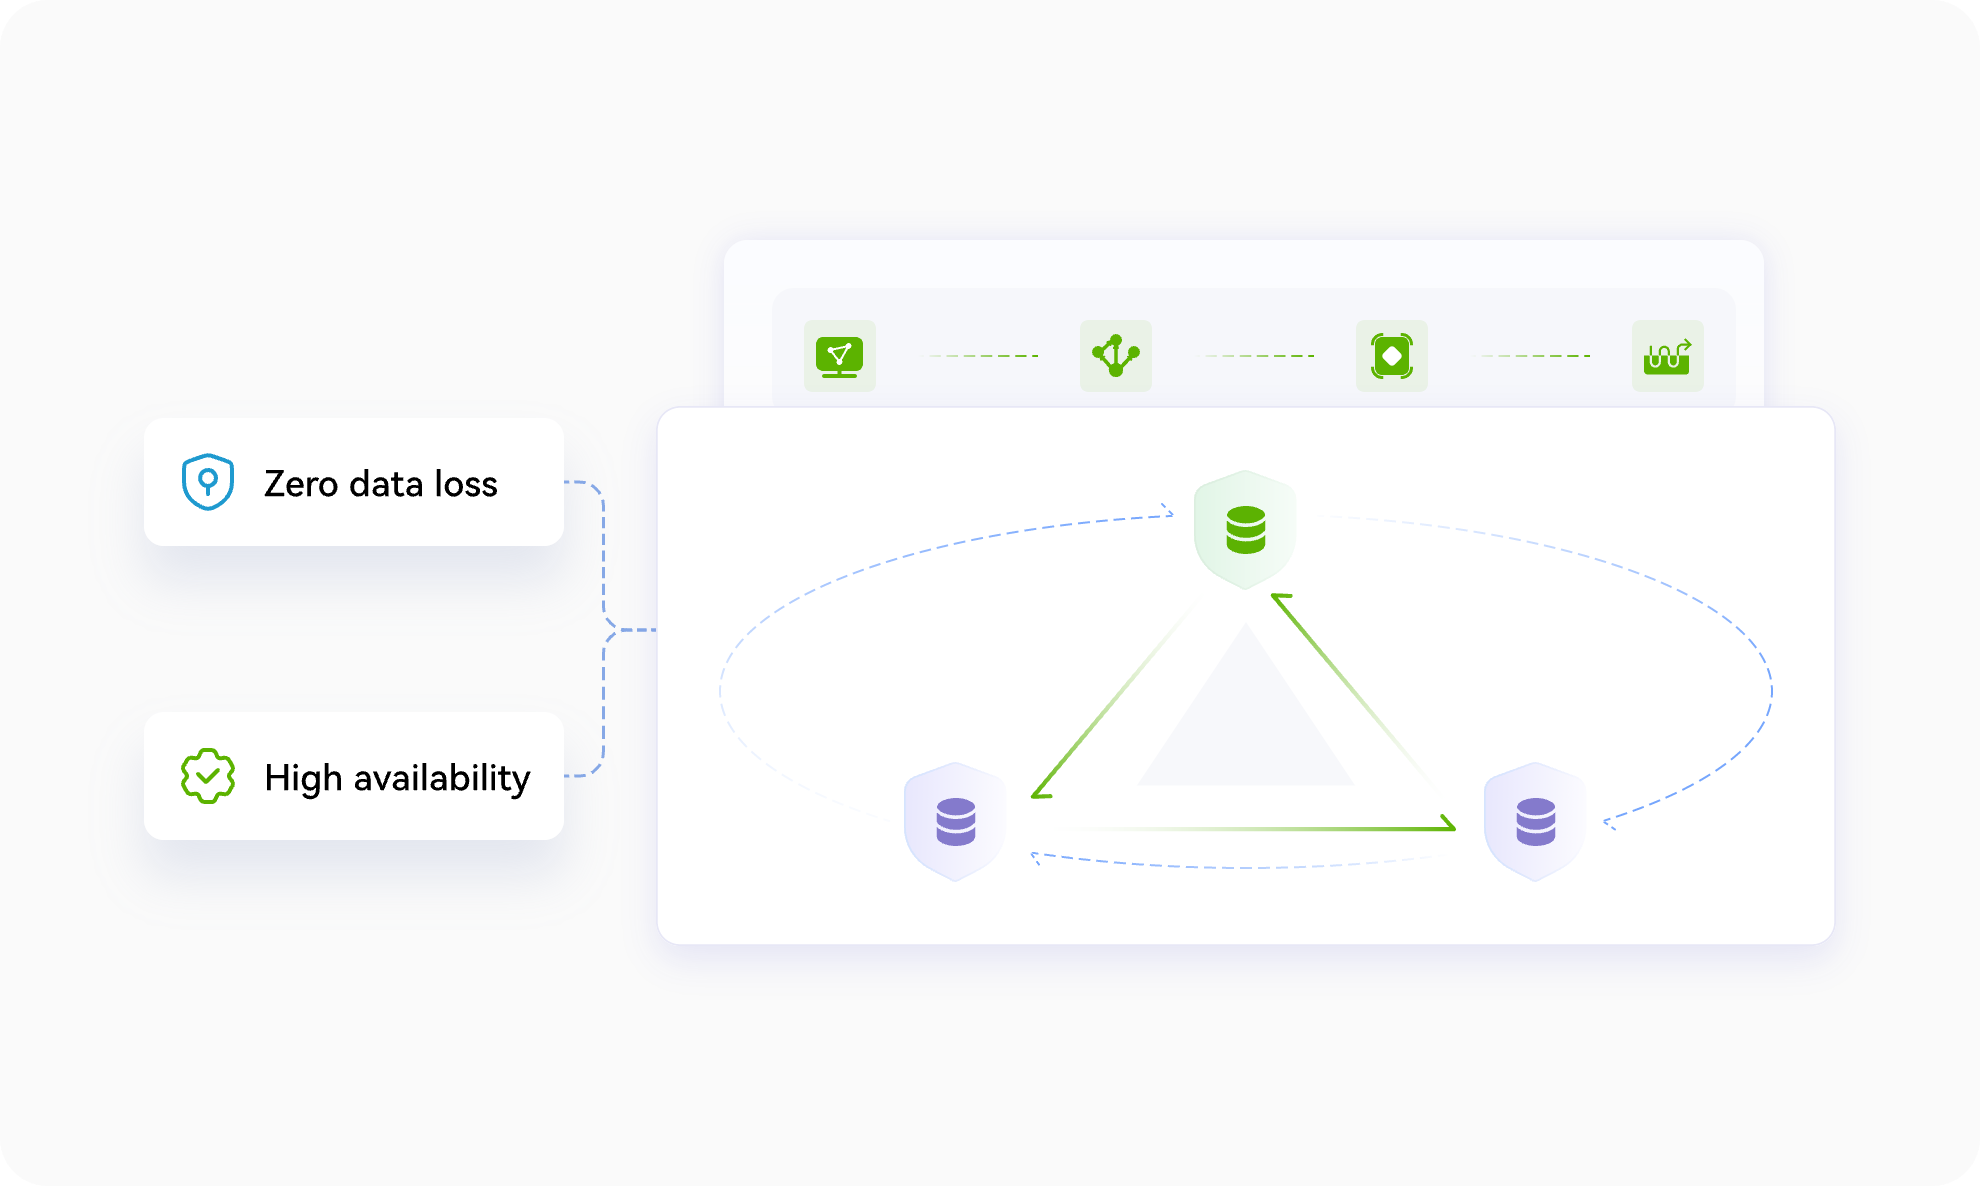
No data loss & Strong data consistency: Three copies of data are stored in a distributed shared storage pool, ensuring zero data loss and strong consistency for multi-point access. 

High availability: Node failover completes in seconds, minimizing service interruptions. The instance remains available even when N−1 nodes fail simultaneously.

Stable performance: GeminiDB has stability designed in, from end to end, with distributed multithreading at the compute layer and remote direct memory access (RDMA) at the storage layer. The RocksDB storage engine is optimized, and cold and hot data separation accelerates hotspot data access. 
Reliability

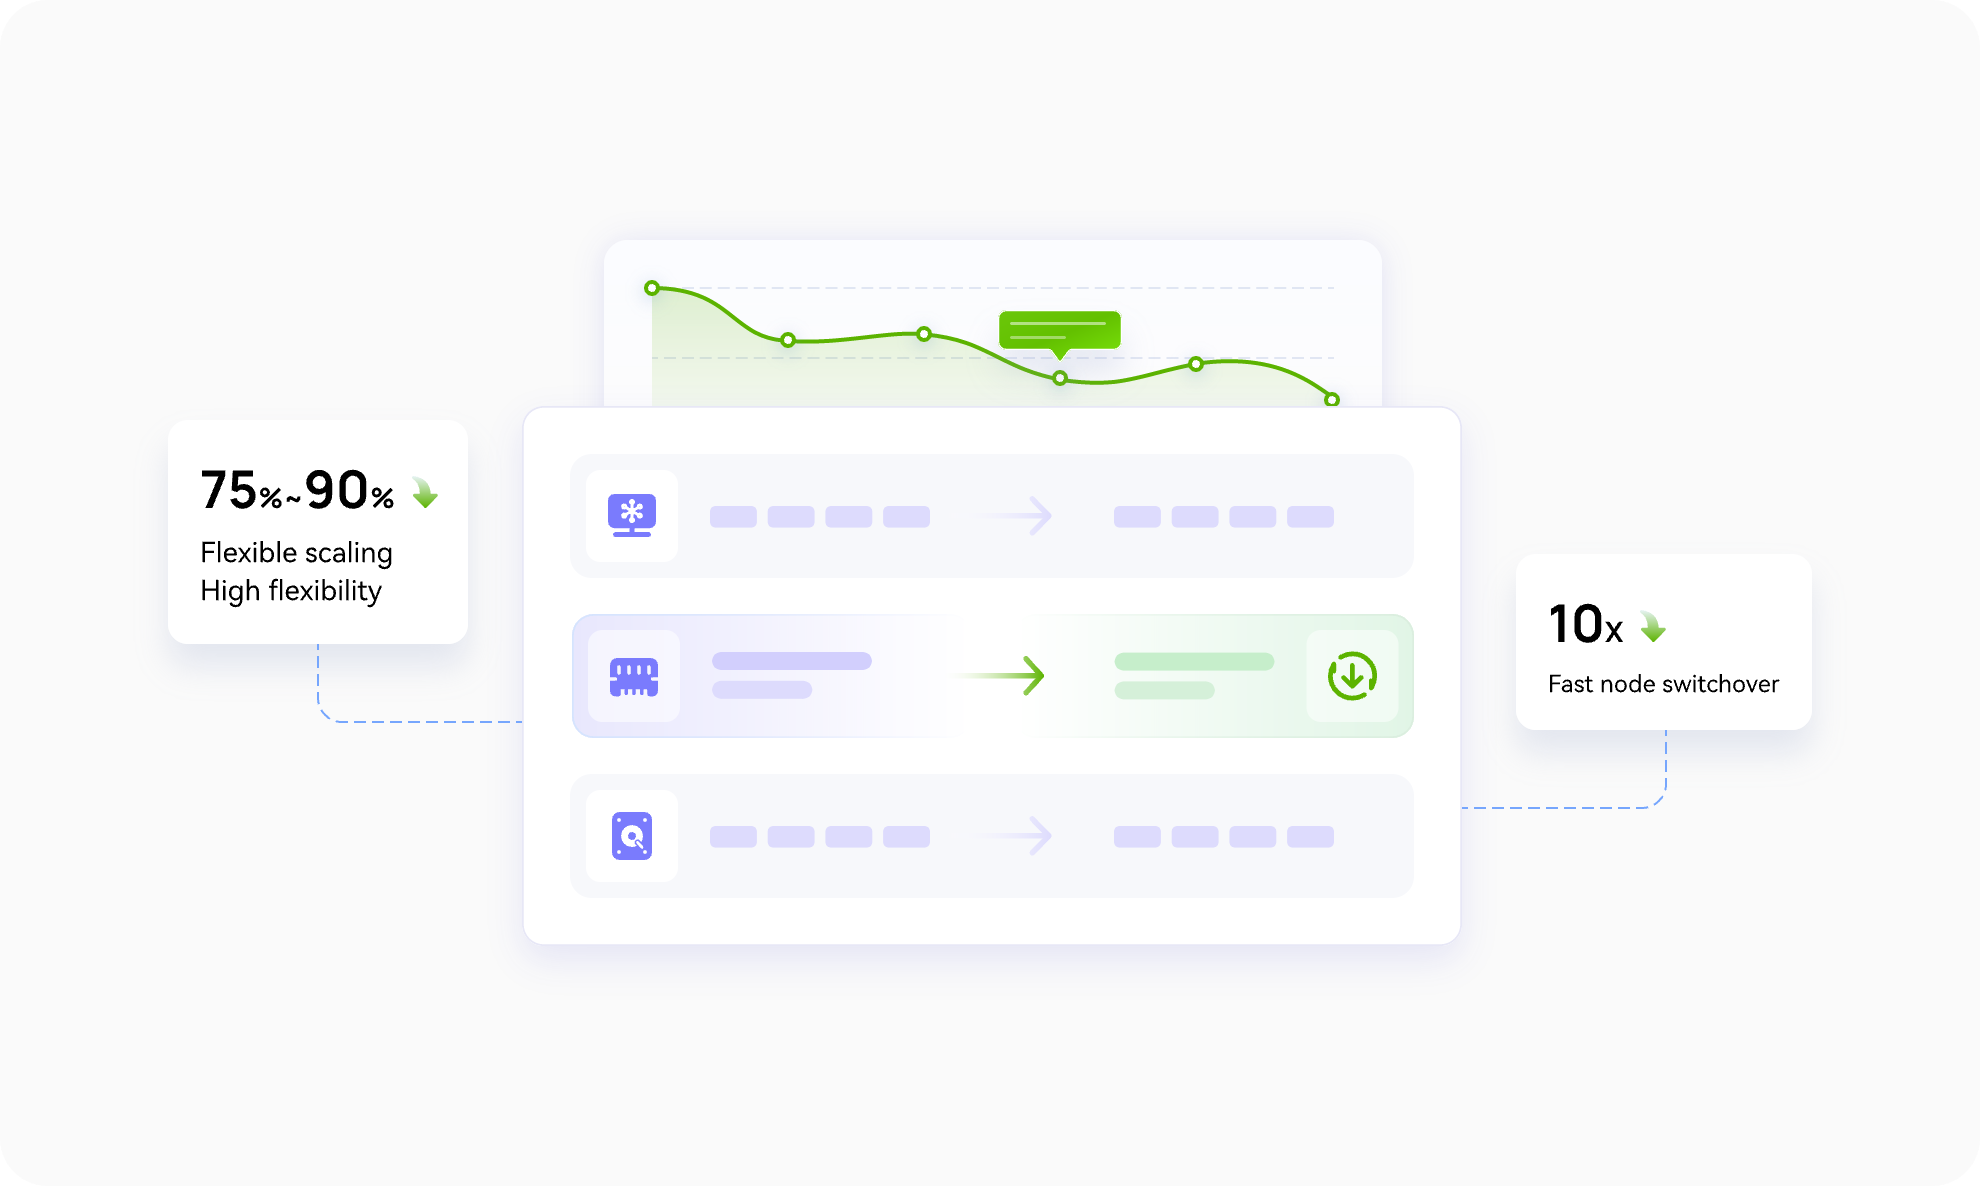
Maximized compute performance: With GeminiDB's decoupled storage and compute, all compute nodes support both reads and writes, reducing standby-node resource waste in traditional deployments and improving compute utilization. 

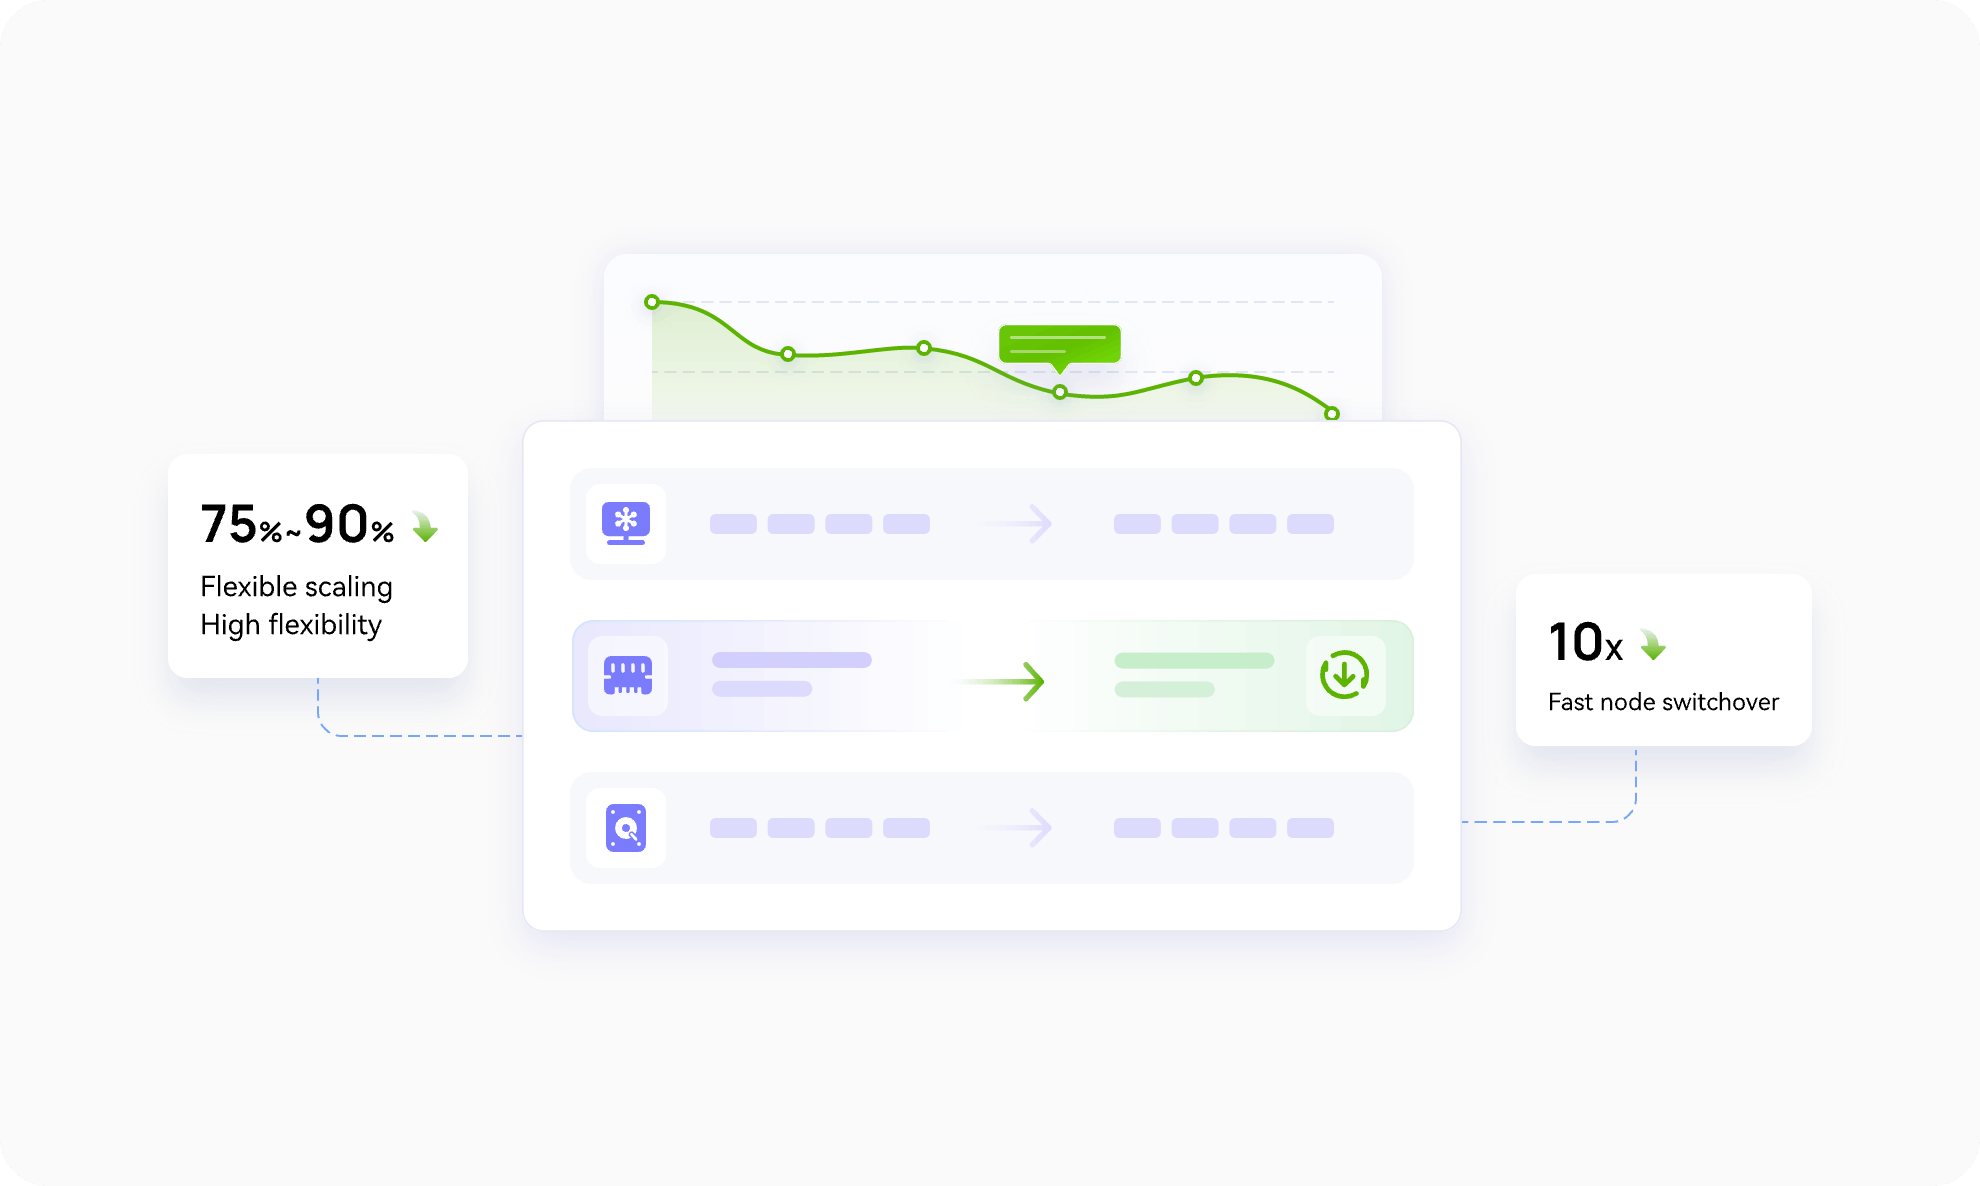
Low memory cost: GeminiDB Redis API has less demanding memory requirements than open-source Redis, which reduces hardware costs by as much as 75% to 90%. 

Low storage cost: For time series data, with the support for adaptive compression and automated hot and cold tiered storage, GeminiDB Influx API requires you to pay only 1/10 of the storage cost of a relational database. 
Cost-Effectiveness
Scalability Scalability Scalability
Reliability Reliability Reliability
Cost-Effectiveness Cost-Effectiveness Cost-Effectiveness

Comprehensive Solutions

Automotive
tab背景图 tab背景图 tab背景图
Zero-ETL Vector Search for Intelligent Driving Data Management

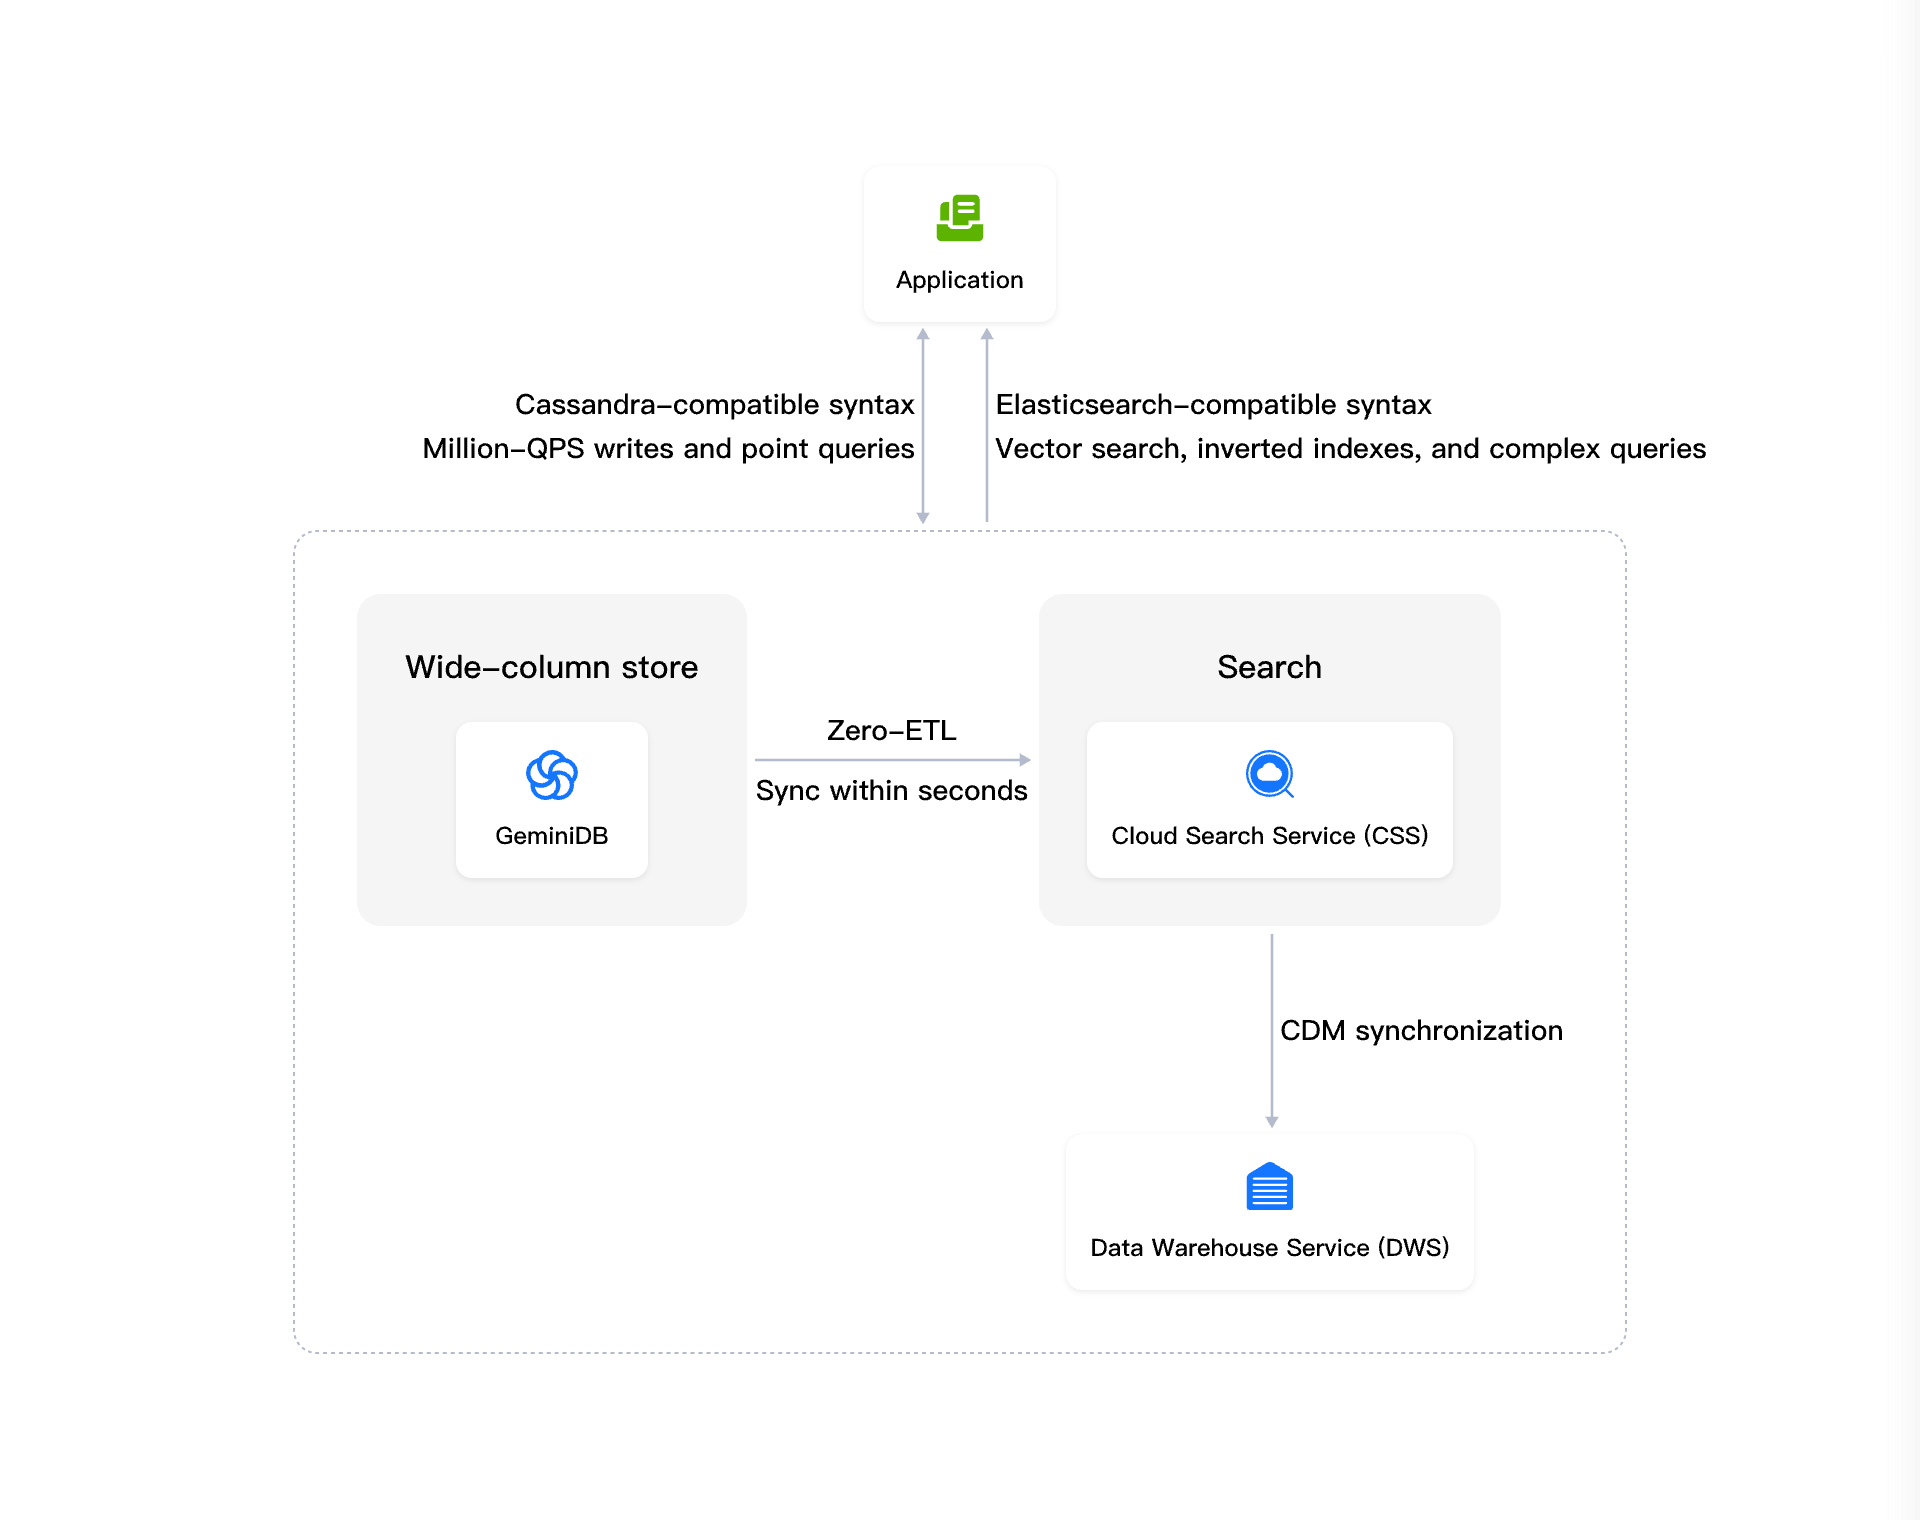
Managing training data for intelligent driving requires high-concurrency ingestion of massive multimodal datasets while supporting complex queries such as precise primary key lookups, full-text search, fuzzy matching, and vector search.

Advantages
High performance

A leaderless distributed architecture combined with LSM-tree-based sequential writes eliminates random I/O bottlenecks, enabling high-concurrency data ingestion at massive scale while maintaining millisecond-level query latency.

Massive-scale data storage

GeminiDB provides reliable persistent storage for hundreds of terabytes of data, with automatic hot/cold data tiering throughout the data lifecycle. Cold historical data is automatically migrated to lower-cost storage media, reducing storage and O&M costs at scale.

Seamless vector search integration

ull and incremental datasets are synchronized directly to the vector search engine, enabling integrated full-text and vector search without complex ETL pipelines. End-to-end GUI-based operations in the console improve development and O&M efficiency by 30%.

AI
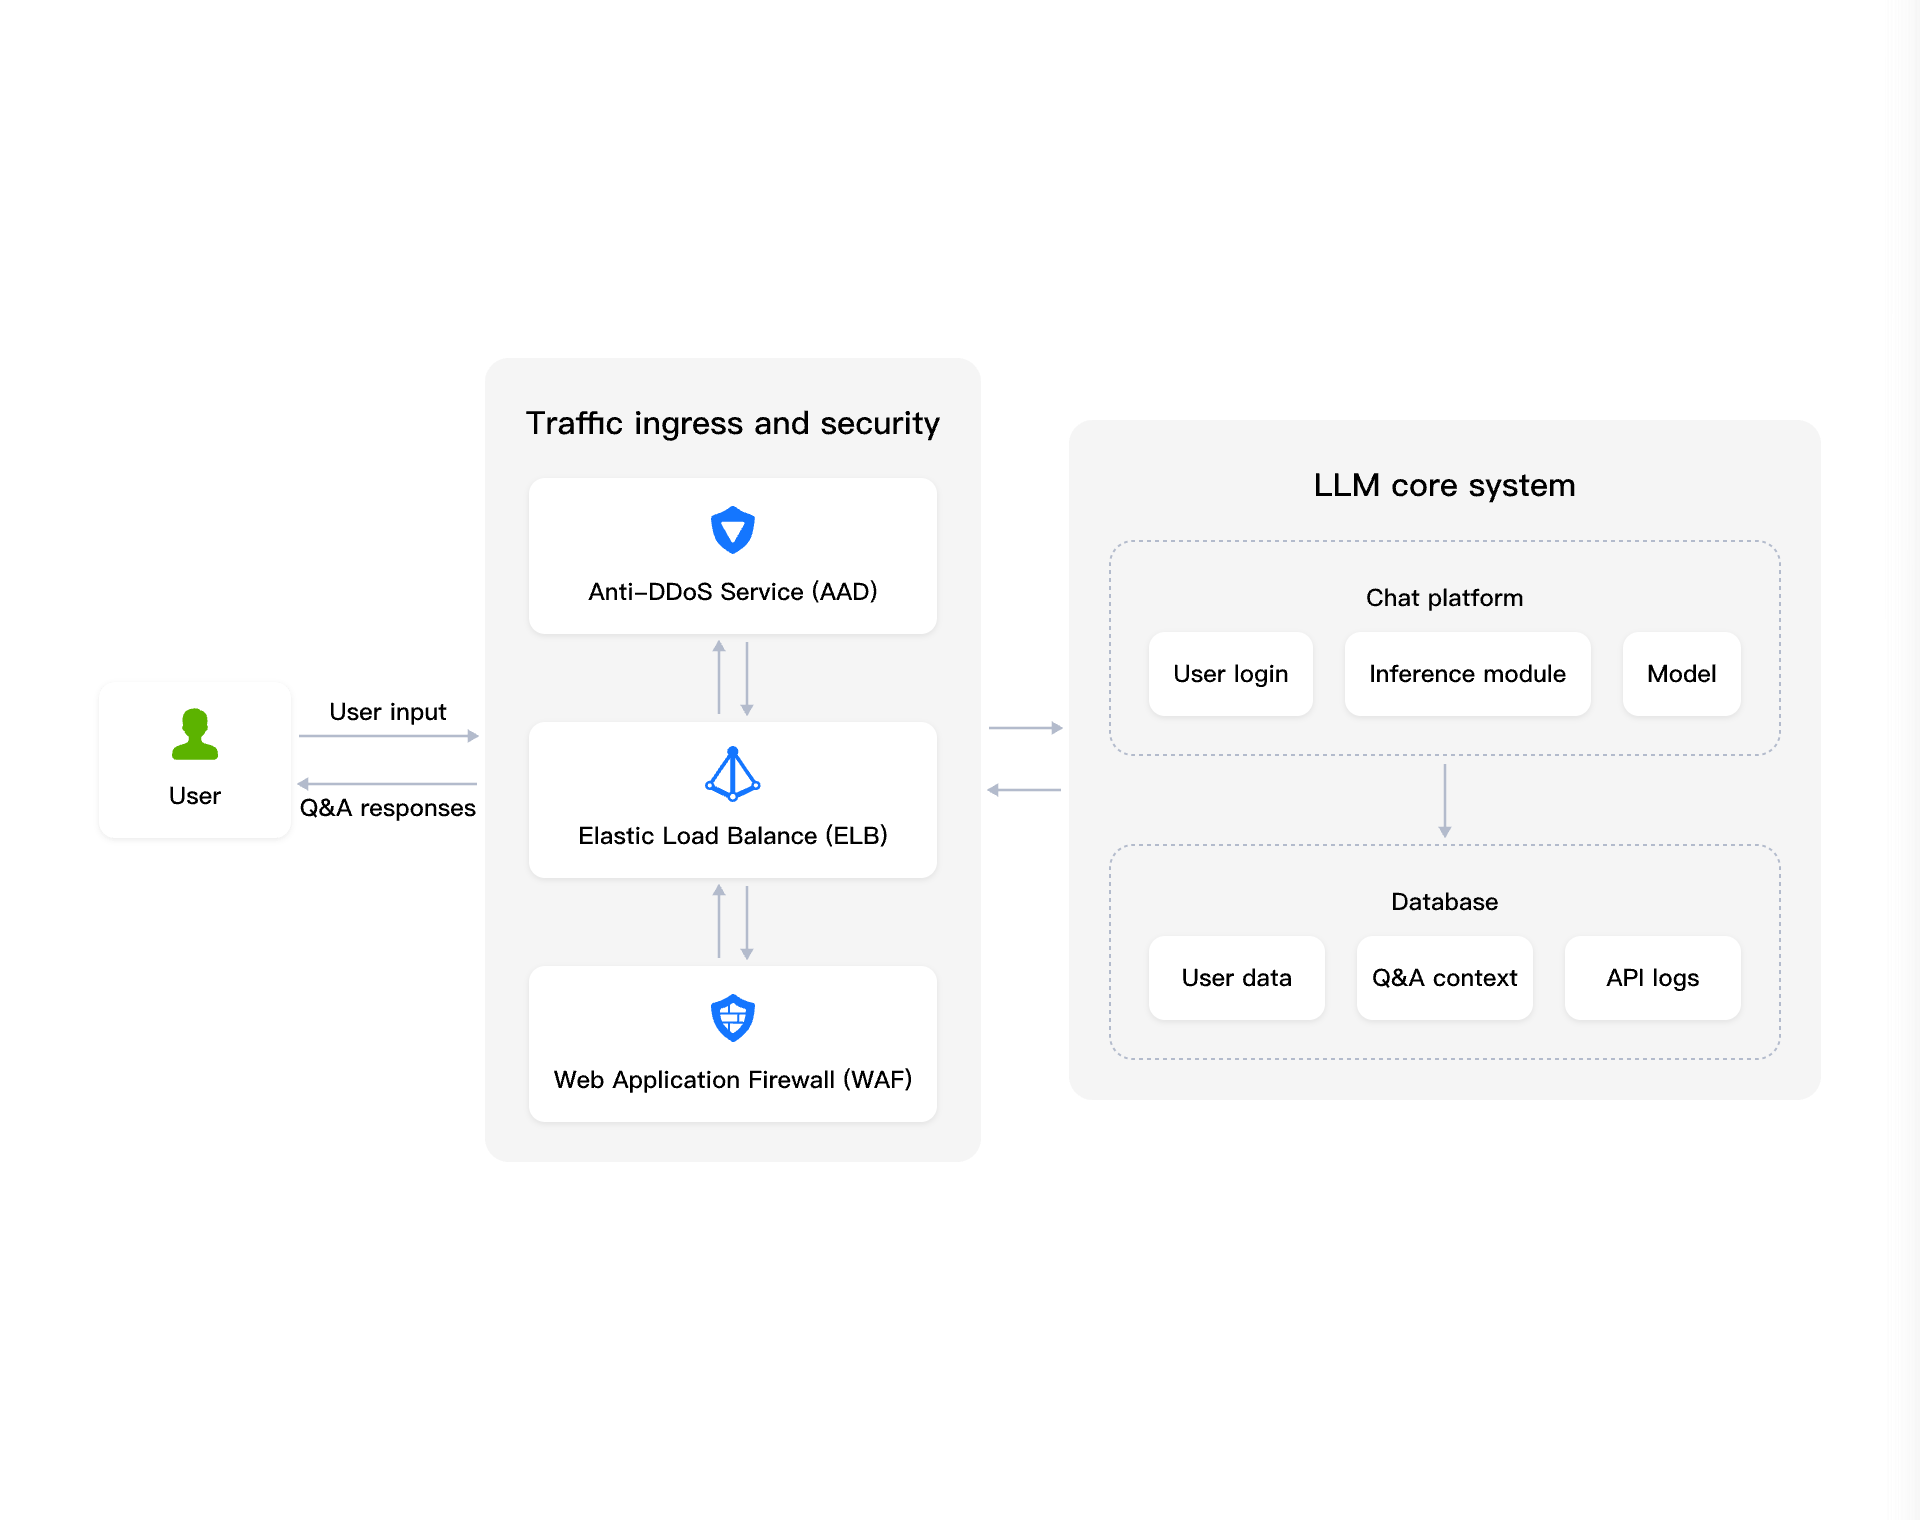
Elastic Scaling, Ultra-Low Latency, and High Reliability for AI Q&A

AI applications must handle massive volumes of real-time conversation context, historical conversations, and user profile data while maintaining millisecond-level response times during traffic spikes and balancing data durability with storage costs.

Advantages
High performance

Automatic hot/cold data tiering keeps hot data in memory while persisting the full dataset to a high-performance storage pool, delivering millisecond-level latency for high-frequency interactions. 

Massive capacity, minimized costs

A multi-tier storage architecture spanning memory, SSDs, and object storage scales smoothly to hundreds of terabytes of capacity while significantly reducing storage and O&M costs.

Cloud-native elastic scaling

Built on a distributed architecture with decoupled storage and compute, the system can scale compute nodes in minutes and storage in seconds without interrupting services. 

Ad Recommendation
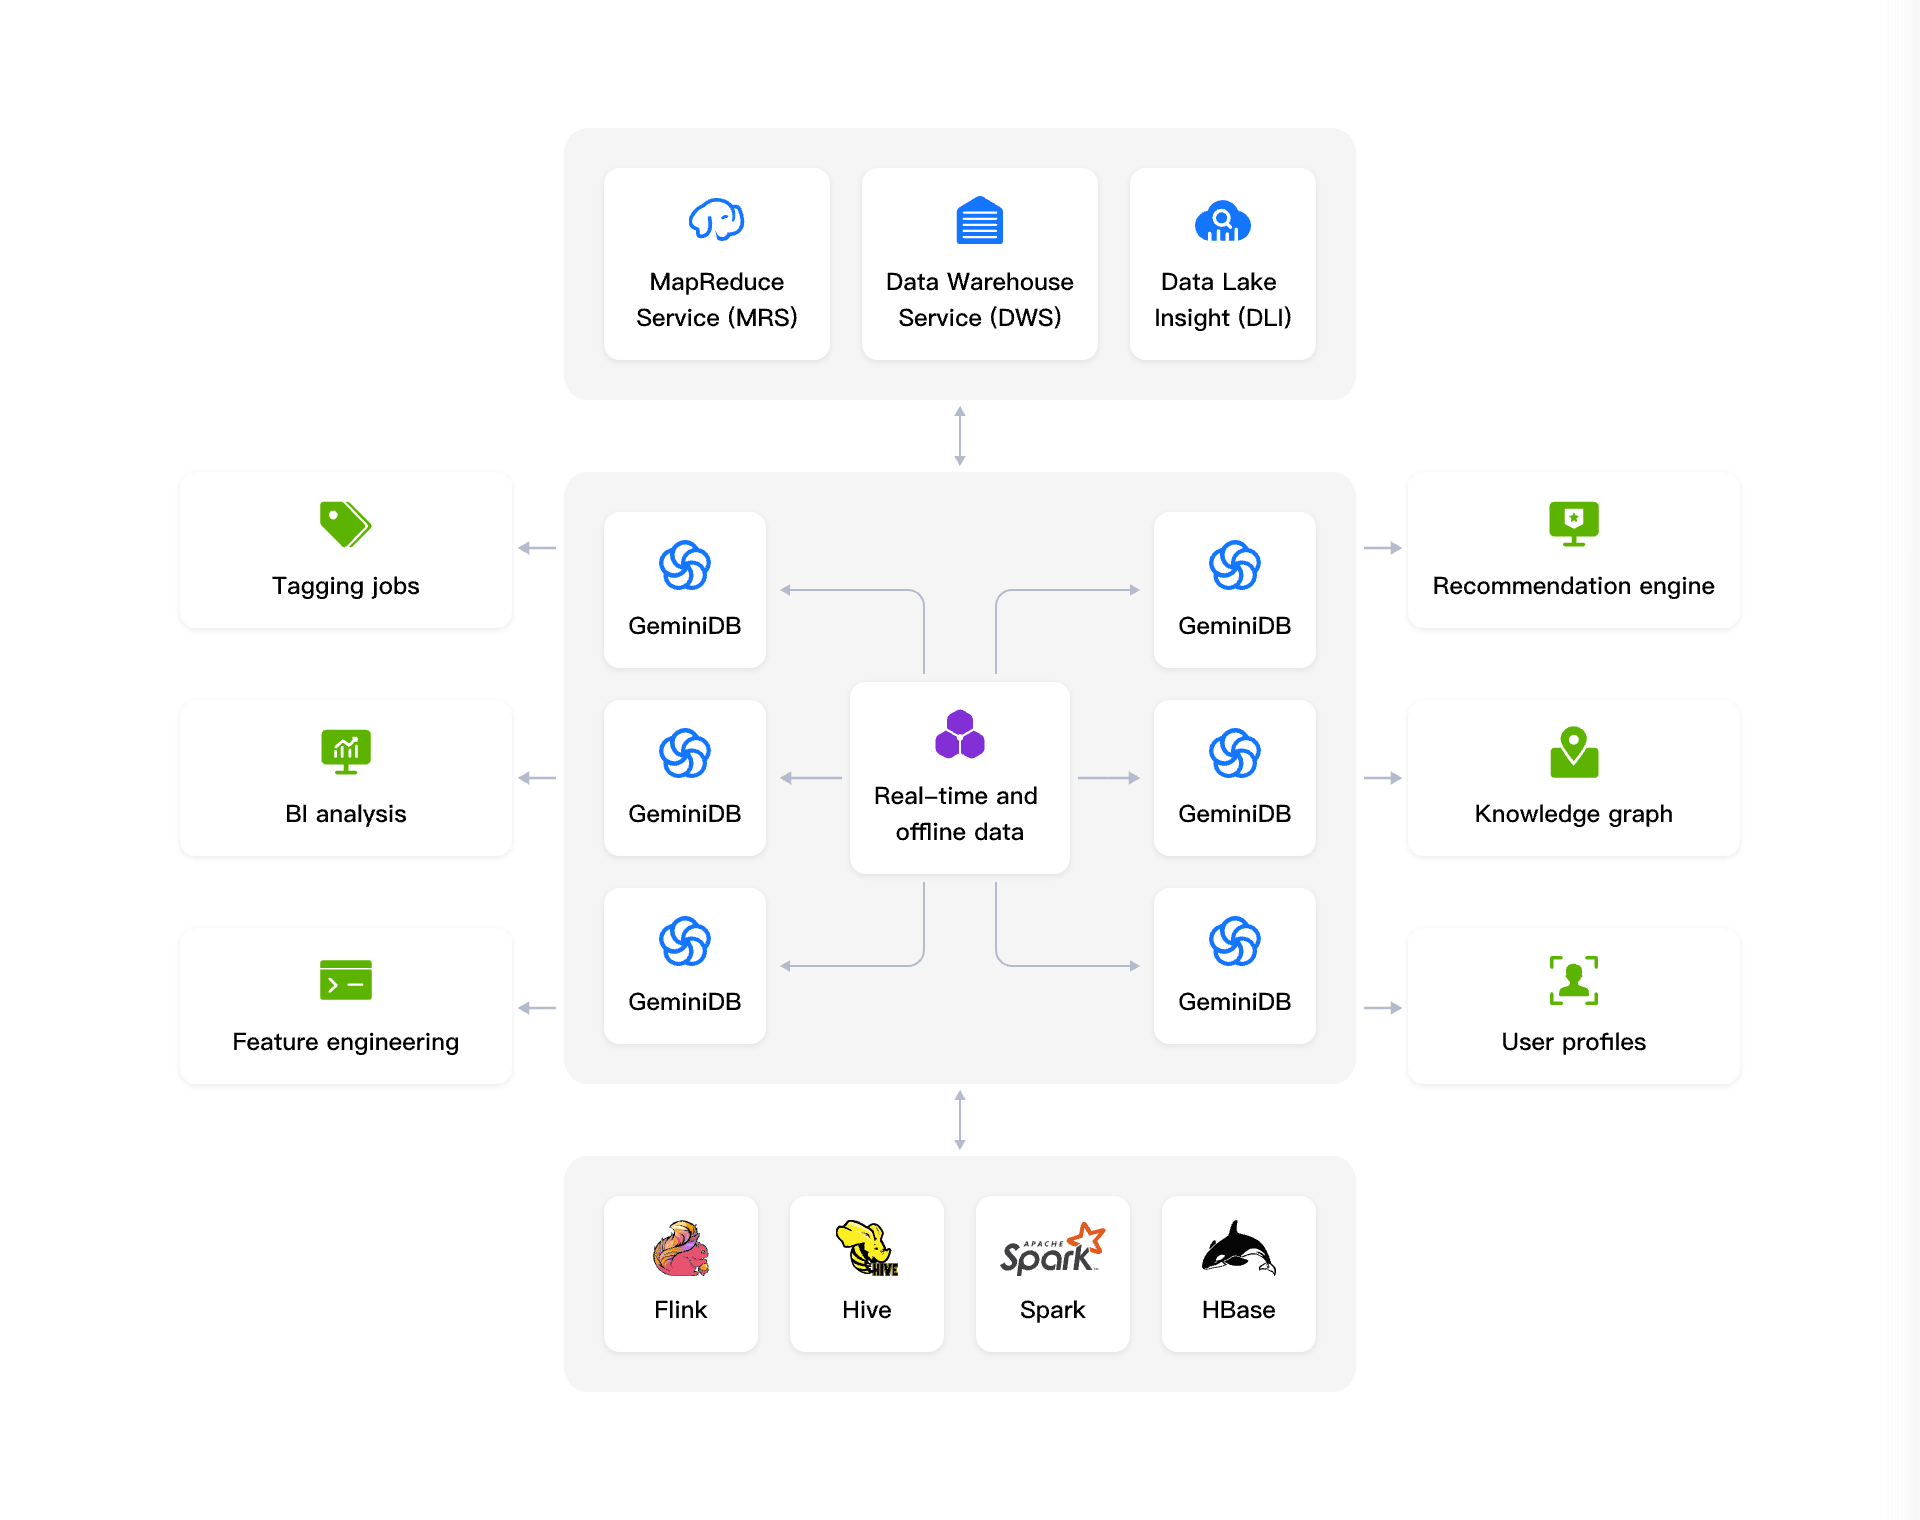
Massive Storage and High-Concurrency Performance for Ad Recommendations

GeminiDB goes beyond the limitations of traditional open-source Redis in memory-only caching scenarios with native support for highly reliable, cost-effective, large-capacity persistent storage. It is designed for core workloads across the end-to-end data pipeline, including precise user profiling, high-dimensional tagging, and feature engineering.

Advantages
High performance

GeminiDB combines an advanced symmetric architecture, in which all nodes support reads and writes, with a multithreaded parallel processing engine to enable high-speed ingestion of massive feature datasets. It delivers up to 5× the data ingestion performance of open-source Redis and supports real-time reads at million-level QPS with millisecond-level latency.

Intelligent tiering for maximum cost efficiency

To meet the storage demands of massive volumes of historical data used for tagging and feature engineering, GeminiDB combines decoupled storage and compute with multi-tier storage. The full dataset is persistently stored with high reliability, while only hot data remains in memory, significantly reducing storage costs compared with traditional fully in-memory solutions.

High reliability

GeminiDB provides strongly consistent, real-time persistence with three-replica data redundancy. In the event of a hardware failure, the cluster can automatically fail over and take over compute workloads within seconds, helping ensure continuous operation of upstream ad bidding services.

Gaming
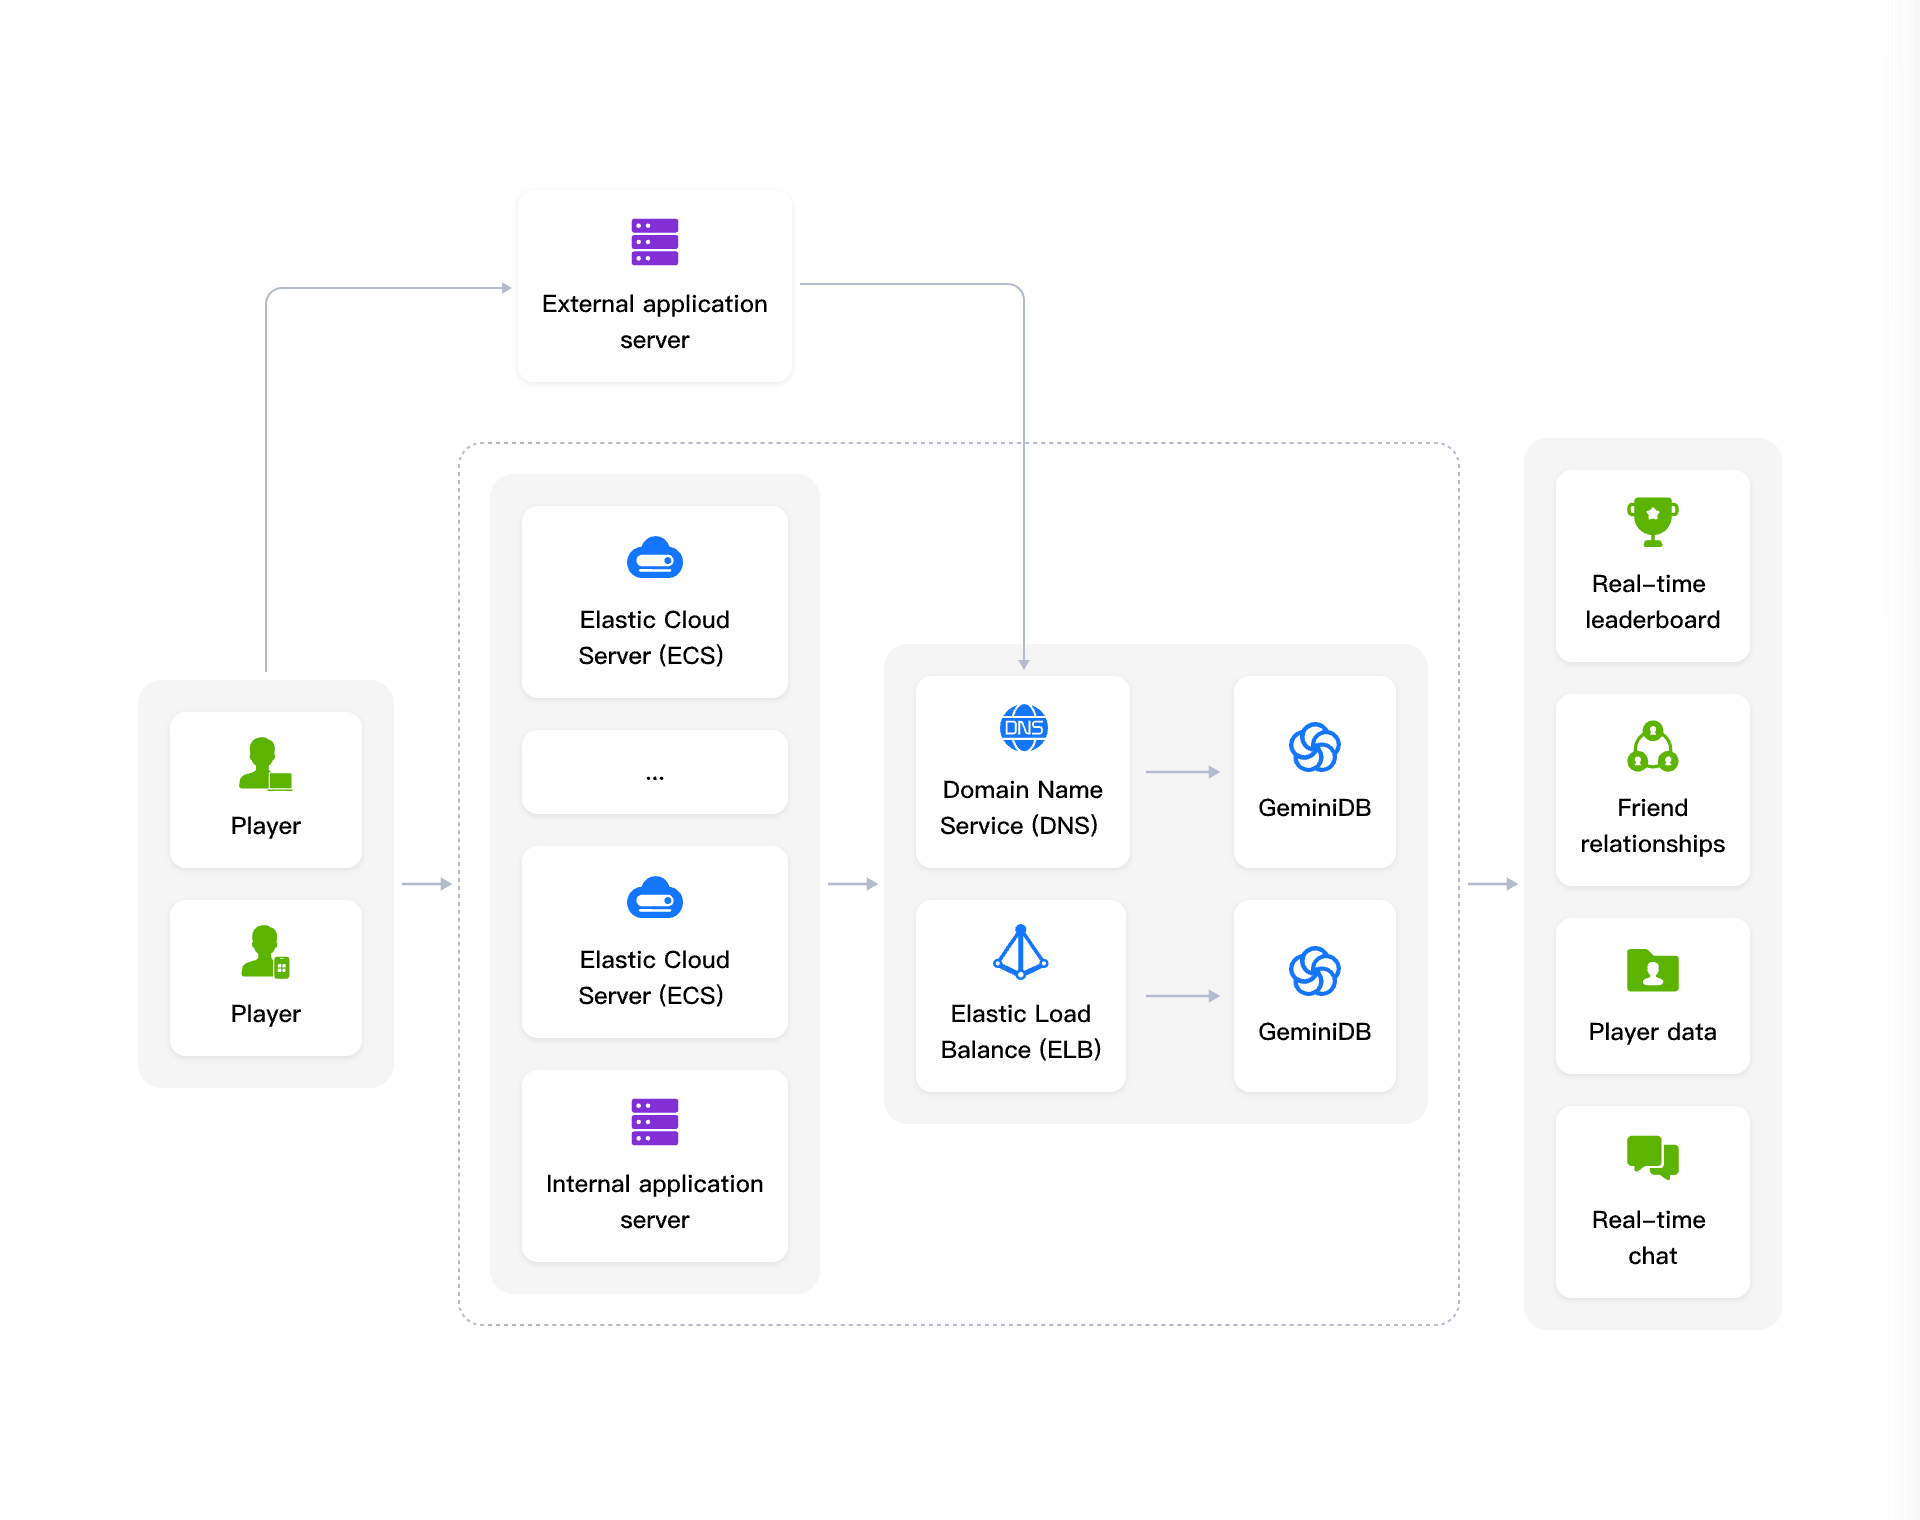
Feature-Rich Data Infrastructure for Agile Game Development

GeminiDB provides a Redis-compatible API with native support for a wide range of data structures, enabling you to efficiently build core game systems. Sorted Sets support real-time leaderboard updates for massive numbers of players, while Pub/Sub enables low-latency, high-concurrency real-time chat. GeminiDB is great for backend servers handling player activity feeds, accounts, and friend systems, efficiently handling and persistently storing player activity data, basic account metadata, and large, complex social graphs.

Advantages
Broad data structure support

Native support for Hash, List, Sorted Set, and other core data structures provides data primitives needed for complex game logic, significantly accelerating development and iteration efficiency.

Rapid scaling for peak traffic

Built to handle the sudden concurrency spikes typical of gaming workloads, GeminiDB supports seamless storage scale-up in seconds and smooth scale-out of compute nodes in minutes, helping maintain responsive player experiences and uninterrupted core services during peak hours.

Low-cost, large-capacity storage

GeminiDB uses decoupled storage and compute combined with a high-performance persistent storage pool to provide hundreds of terabytes of storage. Intelligent hot/cold data tiering keeps hot data in memory while moving cold data to the storage pool, significantly reducing storage costs compared with traditional fully in-memory solutions and providing cost-effective storage for massive volumes of player asset and equipment data.

IoT
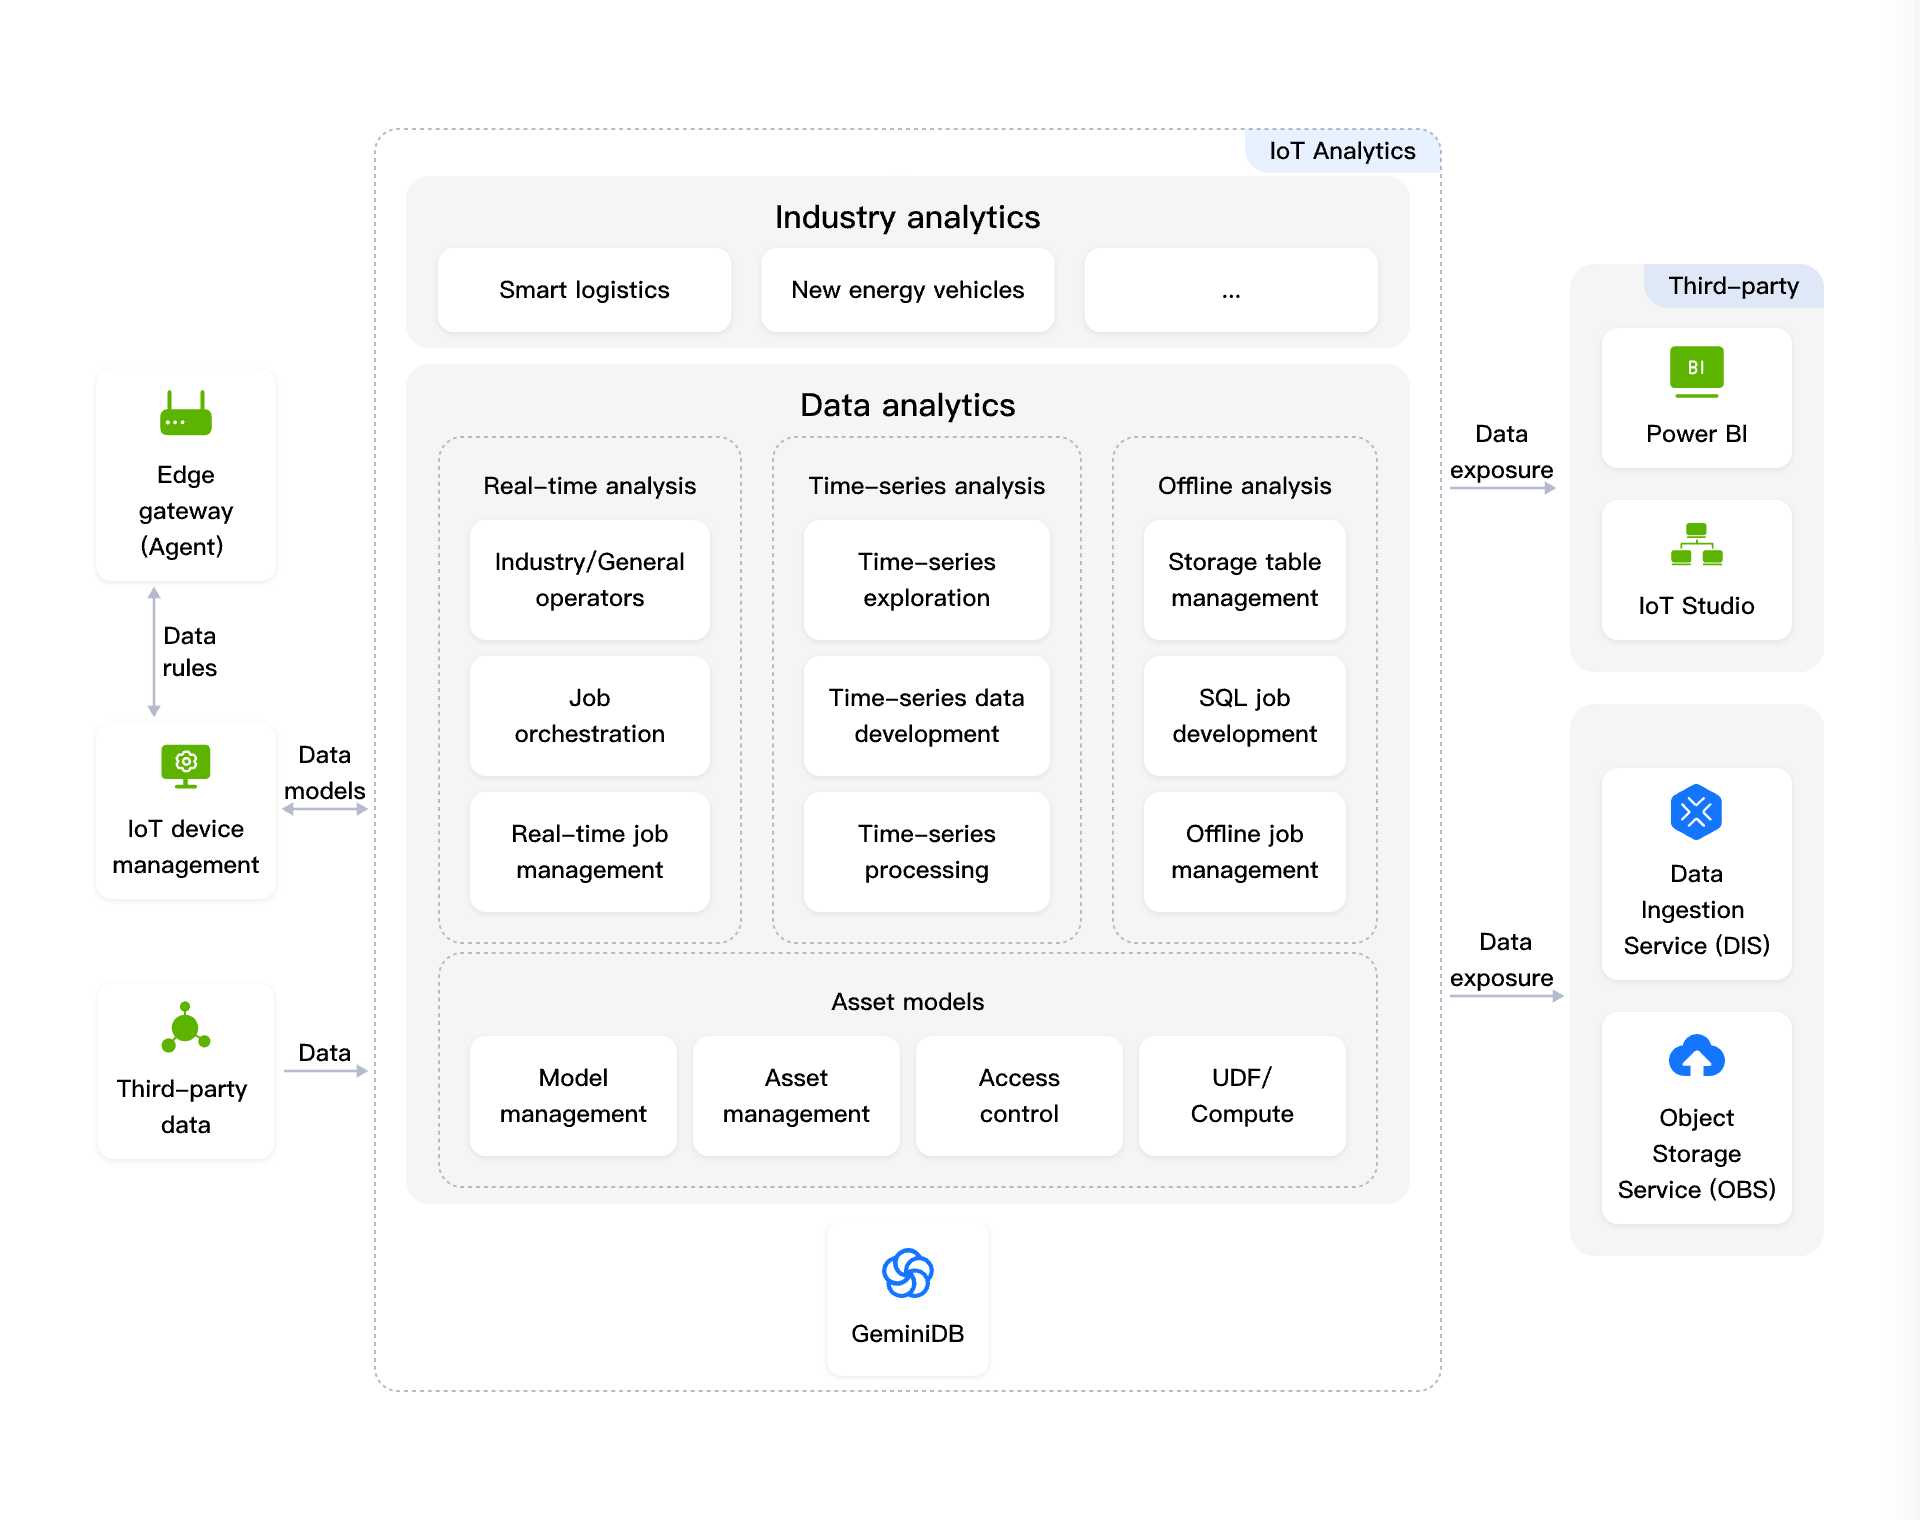
High-Concurrency Time-Series Ingestion for IoT at Scale

Designed for industrial and consumer IoT scenarios such as connected vehicles, smart cities, weather monitoring, and smart wearables, GeminiDB delivers high-concurrency real-time ingestion and full-lifecycle persistent storage for massive volumes of high-frequency, multidimensional sensor data.

Advantages
High write throughput

Purpose-built for time-series workloads, GeminiDB delivers 4.5× the small-batch write performance and 3.3× the large-batch write performance of open-source InfluxDB, easily handling high-concurrency ingestion spikes from massive fleets of IoT devices.

Intelligent hot/cold data tiering for maximum cost savings

Cold data is automatically archived to lower-cost storage media, reducing storage costs by up to 90%. Hot data and cold data are accessed in the same way, requiring no application code changes or adaptation. The hot/cold data age threshold can also be flexibly defined and dynamically adjusted based on business requirements.

Automated data lake export

Built-in efficient data conversion and transfer mechanisms automatically convert online time-series data to standard Parquet files and export them to object storage, where they can serve as a core input source for big data processing engines. This enables deeper mining and complex analysis of massive datasets.

Continuous Innovation with Millions of Customers

Continuous Innovation with Millions of Customers
Travelgate Accelerates Global Hotel Distribution with Huawei Cloud GeminiDB
GeminiDB Powers Immersive Real-Time Interaction for Hundreds of Millions of Mini World Users
GeminiDB Helps MeetYou Enhance Women's Health Services
Travelgate Accelerates Global Hotel Distribution with Huawei Cloud GeminiDB

Travelgate Accelerates Global Hotel Distribution with Huawei Cloud GeminiDB

Travelgate migrated the core database supporting Speed-X from its legacy database to Huawei Cloud GeminiDB. The migration improved performance in core Speed-X scenarios by 50%, keeping Speed-X running reliably even when business traffic increased to five times the original scale. In addition, the O&M and development efficiency was significantly improved.
GeminiDB Powers Immersive Real-Time Interaction for Hundreds of Millions of Mini World Users

GeminiDB Powers Immersive Real-Time Interaction for Hundreds of Millions of Mini World Users

With GeminiDB, Mini World achieved TB-scale data synchronization and updates across multiple regions, reduced overall costs by 60% compared with open-source Redis, and tripled user-profile data capacity. Backed by a high-performance distributed storage pool, GeminiDB provides millisecond-level access to real-time chat data for tens of millions of players, supporting immersive interactions for hundreds of millions of users.
GeminiDB Helps MeetYou Enhance Women's Health Services

GeminiDB Helps MeetYou Enhance Women's Health Services

GeminiDB enables MeetYou to achieve automated fault handling, monitoring by seconds, and intelligent O&M. Elastic resource scaling reduced costs by 20%, helping MeetYou reliably serve over 300 million users. 
Resources

Resources